Prices checked 2026-10-10. AI prices change often, so check the vendor links at the bottom before you budget around them.
Here’s something most people don’t know about AI chat tools: the model has no memory between messages. Every time you hit enter, the app sends the whole thing again. That means the instructions, any documents you pasted, the full conversation so far and your new question. The model reads all of it from the top, every single time.
If you use the AI through an API (a direct connection where you pay per token, roughly per word), you pay for all that re-reading. Coding agents like Claude Code, Codex and Gemini CLI re-send their rules, their tool list and your files on every step. Most of what you pay for is text the model has already seen.
Prompt caching is the fix. All three big AI companies (Anthropic, OpenAI and Google) now offer it. The rest of this post covers what it is, what it costs, and the one habit that makes it work.
What prompt caching is
Think of a teacher grading a 30-page essay that you keep resubmitting with one new paragraph at the end. Without caching, they re-read all 30 pages every time. With caching, they remember the first 29 pages and only read the new bit.
That’s what the AI company does. When it reads the start of your prompt, it saves that work for a few minutes. If your next request starts with exactly the same text, it skips re-reading that part and charges you a much lower price for it.
Three things to know:
- It only matches the start. Caching works on the prefix, the beginning of the prompt. The match has to be exact. Change one character near the top and everything after that point gets read (and billed) at full price again. Anthropic’s docs say it plainly: cache hits need “100% identical prompt segments”.
- It doesn’t change the answer. Same model, same quality. It only changes the price and how fast the reply starts.
- It’s short-lived and private. Caches last minutes, not days, and they’re kept separate per account or workspace. Nobody else can read yours.
What it costs at each company
All three companies price it in a similar way: reading from the cache costs about a tenth of the normal price. Some charge a little extra to write to the cache the first time. The big difference is who turns it on.
| Anthropic (Claude API) | OpenAI (API) – check | Google (Gemini API) | |
|---|---|---|---|
| Who turns it on? | You do. Add one cache_control setting and it caches automatically, or mark exact spots yourself | On by default | On by default (“implicit” caching). You can also create a cache yourself (“explicit”) |
| Reading from the cache | 0.1x the normal input price. Cheaper on the newest models: 0.05x on Opus 5.5 and Sonnet 5.5, 0.025x on Fable 5.1 | 0.1x on GPT-5.6 and later. 0.05x on GPT-6.1 Sol | About 0.1x (for example 3.8 Flash: $0.075 vs $0.75 per million tokens until 2026-12-31; both double on 2027-01-01) |
| Writing to the cache | 1.25x for a 5-minute cache, 2x for a 1-hour cache | 1.25x on GPT-5.6 and later. Free on older models | Implicit: no extra charge. Explicit: a storage fee per hour |
| How long it lasts | 5 minutes, reset every time it’s used. Or 1 hour | At least 30 minutes on GPT-5.6 and later | Implicit: short, not guaranteed. Explicit: 1 hour by default, or whatever you set |
| Smallest prompt it will cache | 512 tokens on the newest models (up to 4,096 on some older ones) | 1,024 tokens on GPT-5.6 and later | 4,096 tokens on Gemini 3.x (2,048 on 2.5) |
| How to check it worked | cache_read_input_tokens in the response | cached_tokens in the response | total_cached_tokens in the response |
| Pricing page | Anthropic API pricing | OpenAi API pricing | Gemini API pricing |
All checked 2026-10-10 against each company’s own docs (links at the bottom).
A token is a chunk of text, roughly three quarters of a word. 512 tokens is about a page. Prompts shorter than the minimum just don’t get cached. There’s no error, and that’s fine, because short prompts are cheap anyway.
On Google’s side, implicit caching saves you money automatically when it happens, but Google says there’s no guarantee it will. If you need guaranteed savings, you create an explicit cache yourself and pay a small storage fee for every hour it exists.
Does it pay off?
Often, yes, even from the second request, as long as the cache actually gets reused.
With Anthropic’s five-minute cache, writing cached input tokens costs 1.25x the normal input price, while reading them costs 0.1x. If you reuse the cache before it expires, the combined cost can be substantially lower than sending the same content repeatedly without caching.
How your bill adds up
Your bill =
    uncached input tokens  x  normal input price
  + cache-write tokens     x  write price
  + cache-read tokens      x  read price
  + output tokens          x  output price
Reading the bill: a small example
Think of it as a receipt with four lines. Every token you send or receive lands on exactly one line, and each line has its own price.
Prices for this example (per million tokens): normal input $2, cache write $2.50, cache read $0.20, output $10.
The setup: you paste a 10,000-token document, ask a 100-token question, and get a 500-token answer. Then you ask a second question about the same document.
Request 1 (the document gets saved to the cache)
| Line | Tokens | Price per million | Cost |
|---|---|---|---|
| Uncached input (your question) | 100 | $2.00 | $0.0002 |
| Cache write (the document) | 10,000 | $2.50 | $0.0250 |
| Cache read | 0 | $0.20 | $0 |
| Output (the answer) | 500 | $10.00 | $0.0050 |
| Total | $0.0302 |
Request 2 (the document comes from the cache)
| Line | Tokens | Price per million | Cost |
|---|---|---|---|
| Uncached input (new question) | 100 | $2.00 | $0.0002 |
| Cache write | 0 | $2.50 | $0 |
| Cache read (the document) | 10,000 | $0.20 | $0.0020 |
| Output (the answer) | 500 | $10.00 | $0.0050 |
| Total | $0.0072 |
The document moved from the “write” line to the “read” line, so the second request costs about a quarter of the first. Without caching, both requests would have paid $0.02 for the document at the normal price.
Two things the example shows:
- Each token is counted once. The document is on the write line or the read line, never also on the normal input line.
- Output doesn’t change. The answer costs $0.005 both times, which is why long answers shrink your savings.
A worked example
Assumptions: an input price of $2 per million tokens (illustrative, so check your model’s current price), a 20,000-token document, and 50 questions. Each question comes within 5 minutes of the last, so the cache stays warm. Only the document is counted here. Your questions and the AI’s answers are billed on top.
Without caching: 50 requests x 20,000 tokens = 1 million tokens. At $2 per million, the document costs $2.00.
With caching: one cache write (20,000 tokens at $2.50 per million = $0.05), then 49 cache reads (980,000 tokens at $0.20 per million = $0.20). Total: $0.25, about 88% less.
Real usage varies, so here’s the same document under different conditions:
| Scenario | Document cost | Compared with no caching |
|---|---|---|
| No caching | $2.00 | Baseline |
| 5-minute cache, 0.1x reads | $0.25 | 88% less |
| 5-minute cache, 0.05x reads (newest models) | $0.15 | 93% less |
| 1-hour cache, 0.1x reads | $0.28 | 86% less |
| One coffee break (the cache expires once) | $0.29 | 85% less |
| A timestamp at the top (every request misses) | $2.50 | 25% more |
Look at the last row. Caching set up wrong costs more than no caching at all. If something at the top of your prompt changes on every request, every request pays the write premium and none get the read discount.
When caching doesn’t help much
- One-off questions where you never reuse the same content.
- Requests made after the cache expires.
- Prompts below the model’s minimum cacheable size.
- Requests where the start of the prompt keeps changing, so the cache never matches.
- Workloads where cache writing or storage costs more than reuse saves.
The one habit: stable stuff first, changing stuff last
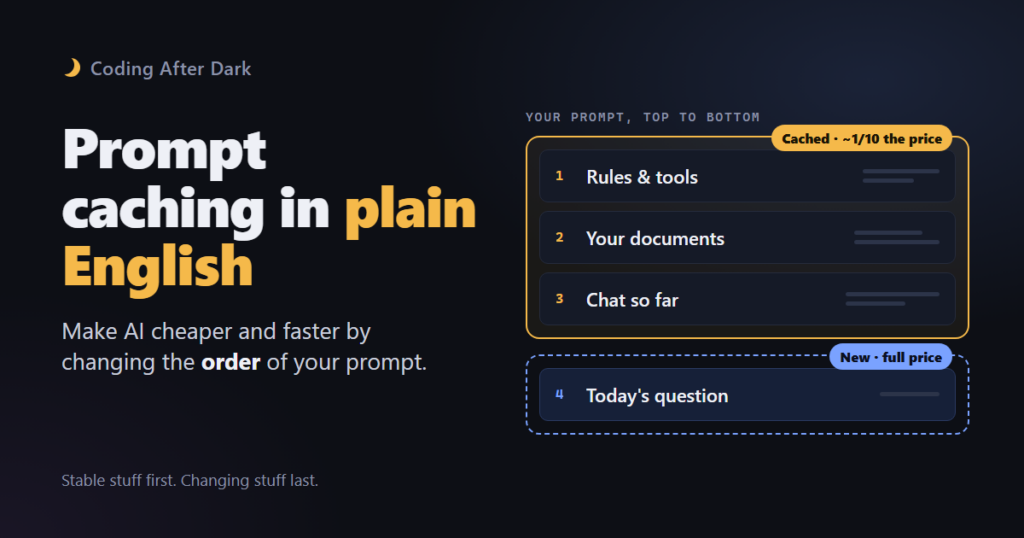
Because caching only matches the start of a prompt, the order you put things in matters more than anything else. Think of packing a suitcase: what you’ll never touch goes at the bottom, and what you need often goes on top.
The order that works:
- Tools and system rules (the instructions that never change)
- Reference material (documents, examples, style guides)
- The conversation so far
- Today’s question
The mistakes that quietly break it:
- Putting the date or time at the top of your instructions. This is the most common mistake. If your system prompt starts “Today is October 10, 2026, 9:41 pm”, the start is different every request, so nothing ever caches. Put the date in the last message instead. Independent write-ups name a timestamp at the top as a common reason the hit rate drops to zero. These breaks are easy to miss: one blog describes a team whose hit rate slid from 72% to 18% over a few months without anyone noticing, as small changes piled up (unconfirmed: that comes from a third-party blog, not a vendor).
- Random IDs at the top. Request IDs, session IDs or tracking codes in the system prompt have the same effect.
- Rewriting earlier messages. Add new messages on the end instead of editing old ones. OpenAI’s guide also warns that summarizing or trimming the conversation resets the cache.
- Changing the tool list. On Claude, changing a tool definition throws away the whole cache, because tools come first. OpenAI suggests keeping the full tool list and limiting which tools can be used, rather than removing them.
- Changing settings mid-conversation. On Claude, switching thinking or effort settings throws away the cached conversation. OpenAI warns that changing reasoning effort can break the cache too, though some newer GPT-6 models have a way to change it without starting over.
How to check: look at the usage numbers in the API response. If the cached-token count stays at zero across repeat requests, something near the top is changing.
Chat app users, this applies to you too. You can’t see the cache in the Claude, ChatGPT or Gemini apps, but the same habits help: paste the big document first, then ask your question. Ask follow-ups in the same chat instead of starting a new one and pasting it again.
Writing prompts that work (and stay cache-friendly)
Caching makes prompts cheaper. Writing them well makes them work. The good news is that the habits fit together.
- Be clear and direct. Write like you’re briefing a smart new coworker: what you want, who it’s for, what “done” looks like. A vague request causes more bad answers than a weak model does.
- Say why. “Keep it short, it’ll be read aloud on a podcast” gets better results than “keep it short”.
- Show examples. Two or three examples of good output beat a long list of rules. Examples are also stable text, so they cache well near the top.
- Use structure. Headings or tags like
<instructions>and<document>help the model tell your instructions apart from the material you gave it. - Ask for a format you can use: a table, a checklist, JSON.
- Cut the shouting. Prompts written for 2024-era models are often full of ALL-CAPS rules. Anthropic’s prompting guide says newer Claude models respond more strongly to instructions, so a rule like “CRITICAL: You MUST use this tool when…” can make them overdo it. Its advice: “dial back any aggressive language” and just write “Use this tool when…”. Trimming old prompts often improves them.
- Test with real examples. Keep a few real inputs and re-run them whenever you change the prompt or the model.
Before and after
Before (breaks the cache, and is vague):
Current time: 2026-10-10 21:41:07. Session ID: 8f3a-22c1.
YOU ARE A HELPFUL ASSISTANT. ALWAYS BE CONCISE!!! NEVER USE JARGON!!!
Summarize this.
[40-page report]
After (stable first, clear about the goal, changing bits last):
You write summaries for Coding After Dark, a podcast for people without
a computer science degree. Summaries are read aloud, so use short
sentences and explain any technical term in plain words.

<report>
[40-page report]
</report>

Today is 2026-10-10. Summarize the report in five bullet points,
then list anything in it that might be out of date.
The instructions and the report sit at the top and never change, so they cache. The date and the specific ask go at the end, where changing them is free.
After After Dark To Try
- If you use an API: send the same long prompt twice within a minute and look for
cache_read_input_tokensorcached_tokensin the response. On Claude, addcache_controlfirst. - Find one changing value (a date, an ID) near the top of a prompt you use, and move it to the end.
- Rewrite one old prompt without the ALL-CAPS, and compare the results.